Fifty questions about one document, five systems, one box
Most of what people ask a decision model is several questions about the same text. So we measured that: 50 questions about one document, on one box.
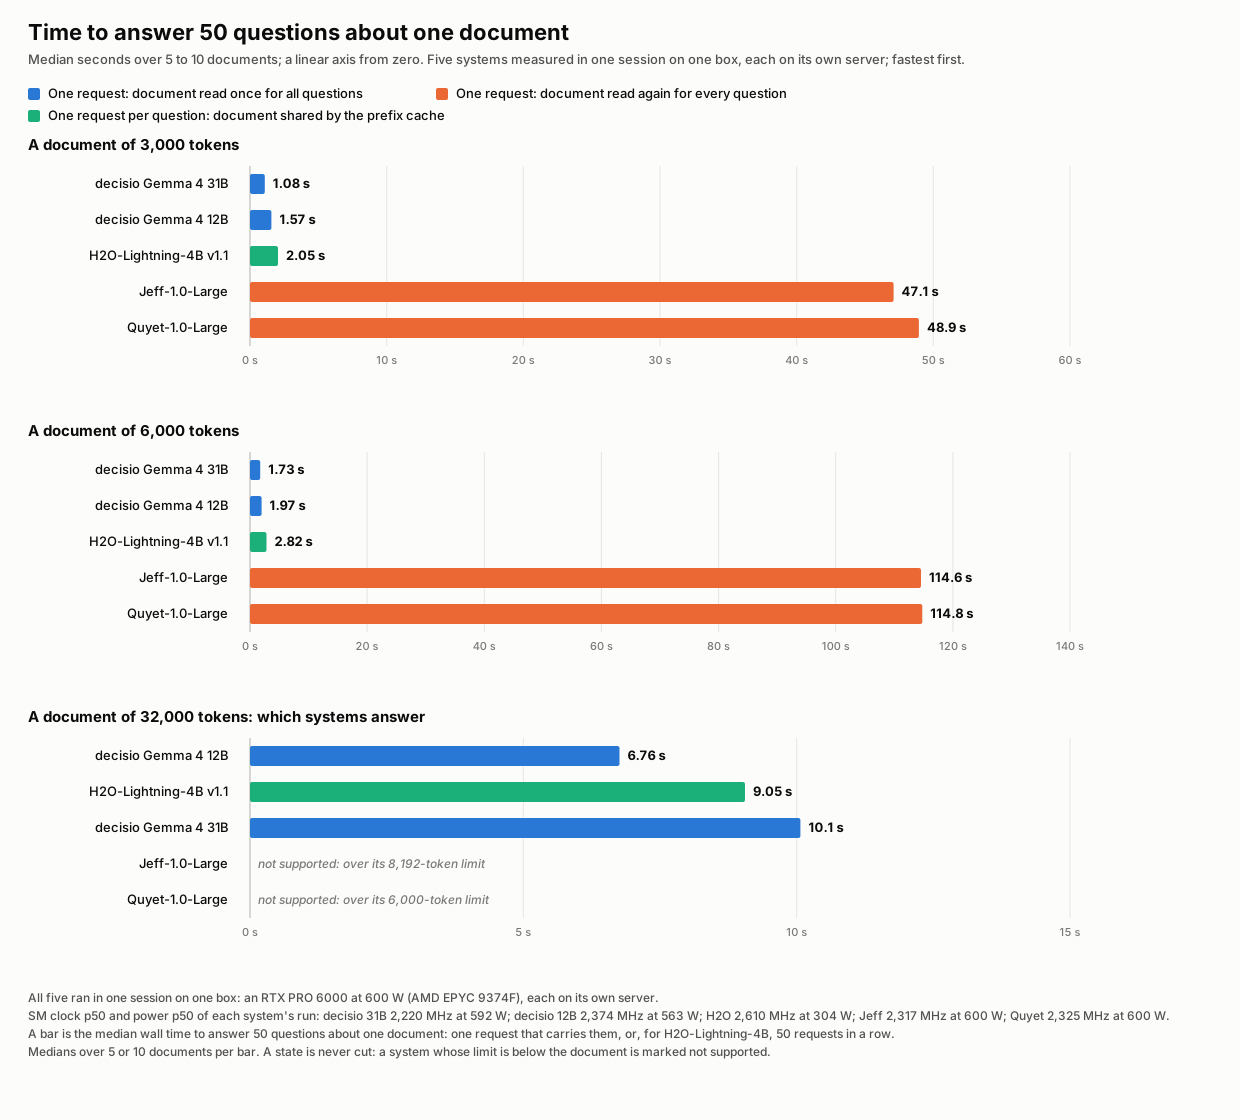
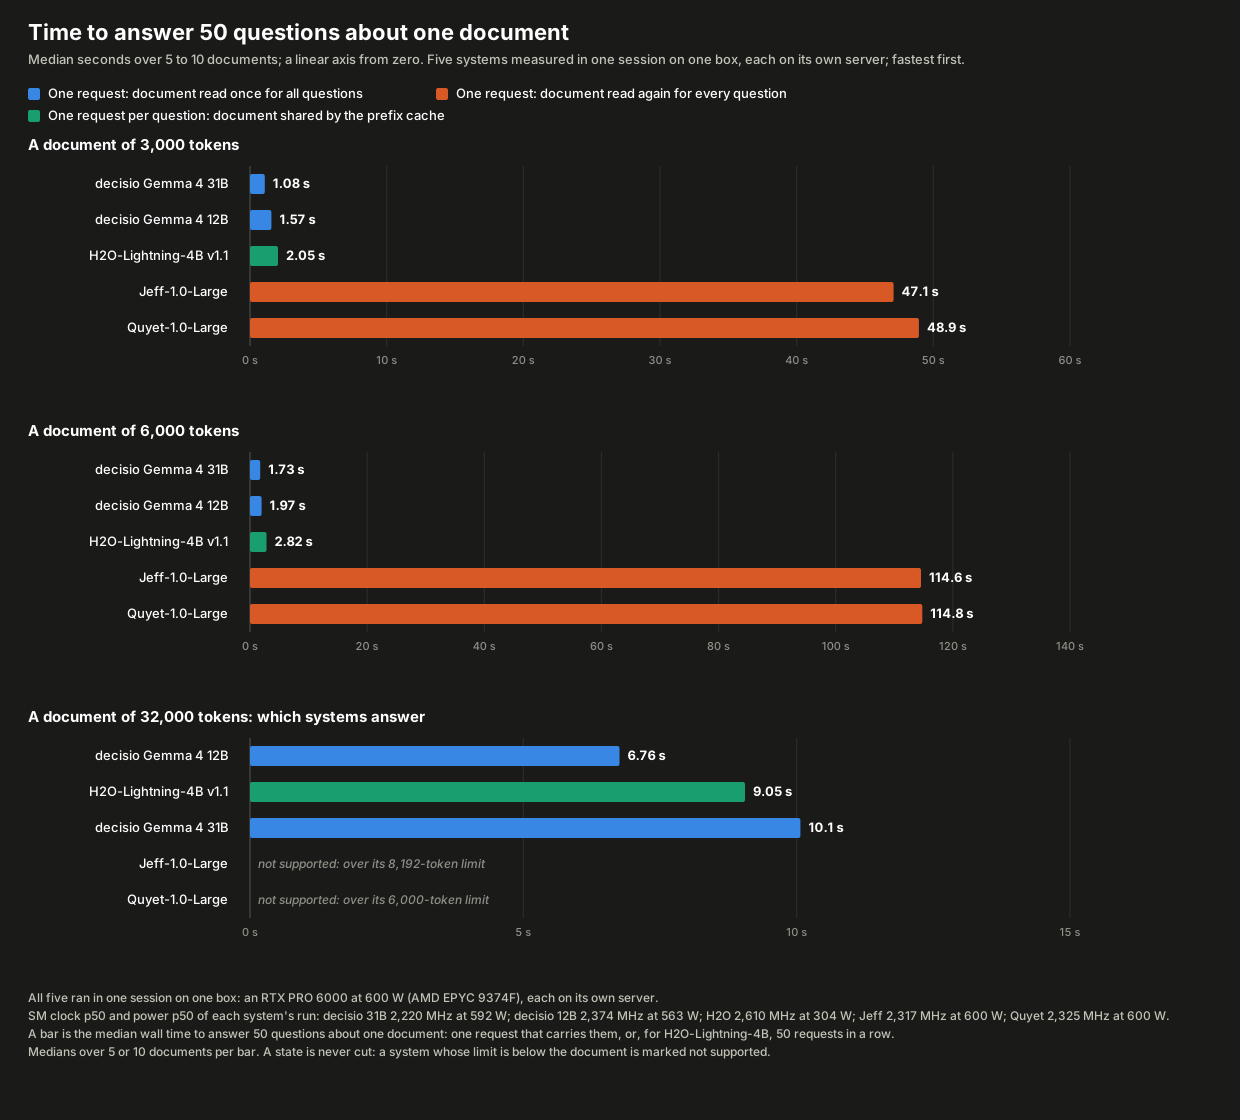
These are the medians in seconds, with the number of documents behind each cell in brackets.
| System | 3,000 tokens | 6,000 tokens | 32,000 tokens | Input limit (tokens) |
|---|---|---|---|---|
| Decisio 31B | 1.08 s (10) | 1.73 s (10) | 10.1 s (5) | 32,768 |
| Decisio 12B | 1.57 s (10) | 1.97 s (10) | 6.76 s (5) | 32,768 |
| H2O-Lightning-4B | 2.05 s (10) | 2.82 s (10) | 9.05 s (5) | 32,000 |
| Jeff-1.0-Large | 47.1 s (5) | 114.6 s (5) | not supported | 8,192 |
| Quyet-1.0-Large | 48.9 s (5) | 114.8 s (5) | not supported | 6,000 |
Jeff-1.0-Large and Quyet-1.0-Large take about 44 times (3,000 tokens) and 66 times (6,000 tokens) as long as Decisio 31B, and neither accepts a 32,000-token document. Both read the document in full for every question. Decisio reads it once, and each further question adds tens of milliseconds. H2O-Lightning-4B shares the document through the prefix cache, with one request per question. The 12B asks its questions one after another, so it is slower than the 31B at 3,000 and 6,000 tokens. At 32,000 tokens the 31B is the slowest of the three that answer.
This compares time, not accuracy. Quyet-1.0-Large and Jeff-1.0-Large score higher than Decisio on JevBench’s capability score (the board’s page on 2026-10-13: 81.69 and 81.50 against 79.57).
One session on one rented box: an RTX PRO 6000 at 600 W and an AMD EPYC 9374F, each system on its own published server, one after another. The documents are synthetic support tickets of 3,000, 6,000 and 32,000 tokens, the same for every system, and the 50 questions come from one fixed pool. An earlier grid, from 2026-10-09, had the systems on different boxes at different clocks, so we do not quote its ratios. If you run one of these systems and think its numbers are off, tell us, and we will share the per-cell data.