Typed decisions, on your own hardware
Jev-level decisions on your own hardware, open source
Typed questions go in. A probability for every option comes out, in one pass.
- 81 ms for one question about a new 300-token text
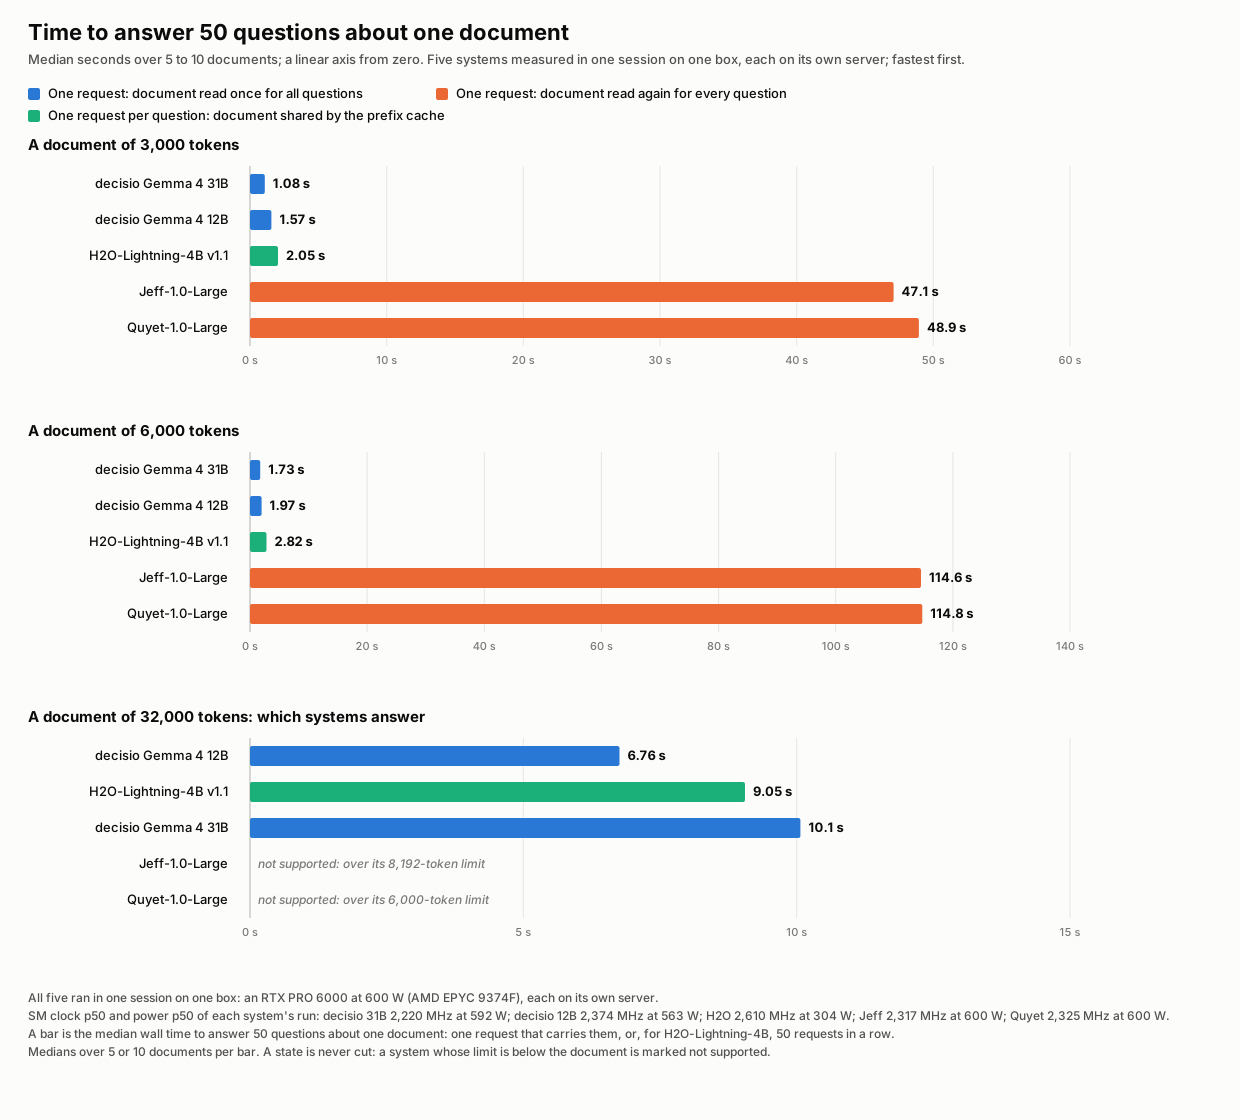
- 1.08 s for 50 questions about a 3,000-token document
- 32,000 tokens in one document
ollama pull aminroudaki/decisio-gemmaIncoming support ticket · record 1 of 60
I was charged twice for October. Both charges are 49.00 EUR, same day. Please refund one.
reads it once91.2 ms
urgentyes/no
Does this ticket need a response within the hour?
queuechoicebilling
Which team should handle this ticket?
impactscorelevel 0.9
Rate the business impact using only the reported facts.
3 of 3 answered · 91.2 ms
On the board
What the public board says
- 2ndof 128 open-weights systems on JevBench v1.6.1
- 70.4on the intelligence axis, against Jev's 63.6, on JevBench v1.6.1
- 73.3on the sealed questions, never published, against Jev's 61.6, on JevBench v1.6.1
Level: the two 95% intervals overlap. JevBench v1.6.1, decisio v0.8.0 rows.
See the board
Second among open-weights systems on JevBench, level with Jev, and the highest-ranked with frozen weights Honest limits
| Open-weights rank | System | Score | 95% interval |
|---|---|---|---|
| 1 | H2O-Lightning-4B v1.1 | 72.52 | 69.79 to 73.79 |
| 2 | decisio v0.8.0, Gemma 4 31B (ours) | 71.69 | 69.86 to 72.81 |
| 3 | Quyet-1.0-Large | 71.39 | 69.84 to 72.21 |
| 4 | decider-12b v2 | 70.88 | 68.54 to 72.21 |
| 5 | decider-12b v1 | 70.42 | 68.09 to 71.63 |
| 6 | torchcast-decision-12b | 69.91 | 67.22 to 71.47 |
| 7 | Winnow-12B Q8 | 68.89 | 66.45 to 70.46 |
| 8 | deck-31B | 68.68 | 67.07 to 69.74 |
| 9 | Cygnet | 68.55 | 64.42 to 69.94 |
| 10 | decisio v0.8.0, Gemma 4 12B (ours) | 68.17 | 57.37 to 69.65 |
| reference | Jev 1.13.0 | 71.49 | 69.14 to 72.40 |
5cd8c1332226.How it works
Read once. Answer fast.
No training: one pass for each question.
One request carries a state and its questions.
The state is read once. Every later question starts from the cache.
Keep the answers above a threshold you pick. Send the rest to a person or a larger model.
Speed, measured on one box
Many questions about one document
Fifty questions about one document, on one box.
- about 44 timesas long for Jeff and Quyet as for Decisio 31B, at 3,000 tokens, on the same box
- 66 timesas long for them at 6,000 tokens
- 10.1 sfor Decisio 31B to answer 50 questions about a 32,000-token document, which neither Jeff nor Quyet accepts
Which systems accept your document
The exact wording, from the facts
On one box, Decisio 31B answers 50 questions about one 3,000-token document in 1.08 s and about one 6,000-token document in 1.73 s; Decisio 12B takes 1.57 s and 1.97 s, and H2O-Lightning-4B 2.05 s and 2.82 s.
On one box, Jeff-1.0-Large and Quyet-1.0-Large, the two systems ranked above Decisio on JevBench's capability score, take about 44 times (3,000 tokens) and 66 times (6,000 tokens) as long as Decisio 31B to answer 50 questions about one document, and neither accepts a 32,000-token document.
At 32,000 tokens, Decisio 31B answers 50 questions about one document in 10.1 s, Decisio 12B in 6.76 s and H2O-Lightning-4B in 9.05 s; Jeff-1.0-Large accepts documents of up to 8,192 tokens and Quyet-1.0-Large up to 6,000, so neither accepts a 32,000-token document.
On one box, the first question about a new 3,000-token document takes a median of 112 ms on H2O-Lightning-4B, 295 ms on Decisio 12B, 490 ms on Decisio 31B, and 895 ms on Jeff-1.0-Large and 895 ms on Quyet-1.0-Large.
The board, column by column
JevBench, axis by axis
The ten highest open-weights systems and Jev on the public board, each cell shaded by its rank in the column; higher is better on every axis.
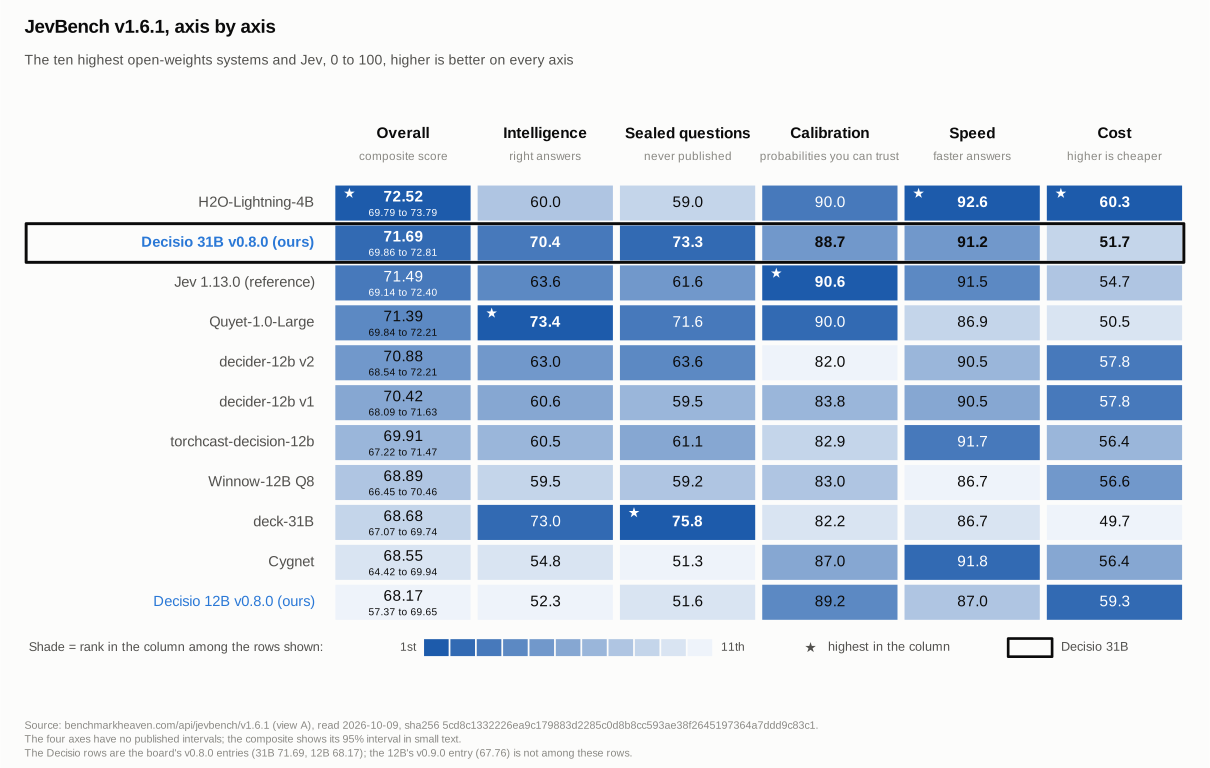
- On JevBench v1.6.1, among the ten highest open-weights systems and Jev: 2nd overall, 2nd on sealed questions (73.3, never published) and 3rd on intelligence (70.4 against Jev's 63.6).
- On JevBench v1.6.1, within 2 points of the highest on calibration (88.7; Jev 90.6) and on speed (91.2; H2O-Lightning-4B 92.6).
- On JevBench v1.6.1, 9th on the board's cost axis (51.7; H2O-Lightning-4B 60.3 is highest). On your own hardware you pay for the card, not per token.
Every number
| System | Overall | Intelligence | Sealed questions | Calibration | Speed | Cost |
|---|---|---|---|---|---|---|
| H2O-Lightning-4B | 72.52 | 60.0 | 59.0 | 90.0 | 92.6 | 60.3 |
| Decisio 31B v0.8.0 (ours) | 71.69 | 70.4 | 73.3 | 88.7 | 91.2 | 51.7 |
| Jev 1.13.0 (reference) | 71.49 | 63.6 | 61.6 | 90.6 | 91.5 | 54.7 |
| Quyet-1.0-Large | 71.39 | 73.4 | 71.6 | 90.0 | 86.9 | 50.5 |
| decider-12b v2 | 70.88 | 63.0 | 63.6 | 82.0 | 90.5 | 57.8 |
| decider-12b v1 | 70.42 | 60.6 | 59.5 | 83.8 | 90.5 | 57.8 |
| torchcast-decision-12b | 69.91 | 60.5 | 61.1 | 82.9 | 91.7 | 56.4 |
| Winnow-12B Q8 | 68.89 | 59.5 | 59.2 | 83.0 | 86.7 | 56.6 |
| deck-31B | 68.68 | 73.0 | 75.8 | 82.2 | 86.7 | 49.7 |
| Cygnet | 68.55 | 54.8 | 51.3 | 87.0 | 91.8 | 56.4 |
| Decisio 12B v0.8.0 (ours) | 68.17 | 52.3 | 51.6 | 89.2 | 87.0 | 59.3 |
The highest value in each column is in bold. Source: the board's file for revision v1.6.1.
Routing
Use the probability
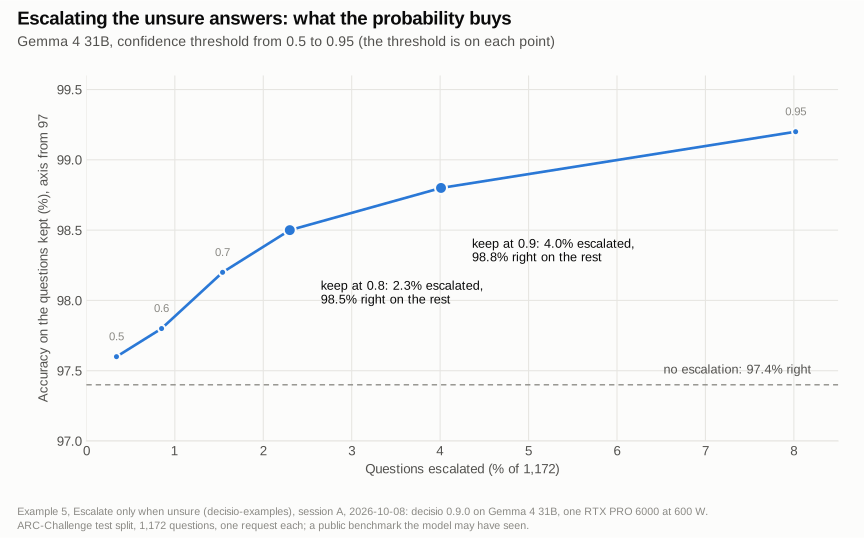
Keep the answers above a threshold you pick and send the rest to a person or a larger model. Example 5 measured what that buys.
Every threshold, as measured
| Rule | Escalated | Right on the rest | 95% interval | Confidently wrong (wrong, kept) | Wrong answers escalated |
|---|---|---|---|---|---|
| No escalation | 0 (0.0%) | 97.4% | not applicable | 31 | 0 of 31 |
| Keep at 0.8 or more | 27 (2.3%) | 98.5% | 97.6% to 99.1% | 17 | 14 of 31 |
| Keep at 0.9 or more | 47 (4.0%) | 98.8% | 98.0% to 99.3% | 13 | 18 of 31 |
Why
Why Decisio
Many questions, one read
Every question in a request is scored from one read of your text: the same choice as one question at a time on every item measured, probabilities within 0.0073.
Long prompts, many options
Prompts up to 32,768 tokens and 255 options per question.
Your hardware, no per-token bill
It runs on your own GPU, Mac or laptop; the cost is the card, not a bill per token.
Demos
Watch it decide
Decisions in real time, from Decisio's own demos and one recorded run. Each clip is cut at the speed it happened. Nothing is sped up.
The driving clip draws map data from OpenStreetMap (ODbL, © OpenStreetMap contributors).
Get started
Four ways in, one command each.
# the Gemma 4 12B base, for 16 GB laptopsollama pull aminroudaki/decisio-gemma# the Qwen baseollama pull aminroudaki/decisioThe Ollama guide, and every path.
git clone https://github.com/aminry/decisiocd decisiouv sync --extra serve --frozenuv run python -m decisio.serve.vllm_engineThe GPU guide, and every path.
uv build --wheel # the image installs this wheeldocker compose up --build # needs the NVIDIA Container Toolkitcurl http://127.0.0.1:8000/health # answers once the first start has fetched the checkpointThe Docker guide, and every path.
uv sync --extra mlxuv run python -m decisio.serve.vllm_engine --backend mlx --model mlx-community/Qwen3.6-35B-A3B-6bituv run python -m decisio.serve.vllm_engine --backend mlx --base gemma-4-12b --model mlx-community/gemma-4-12B-it-6bituv run python -m decisio.serve.vllm_engine --backend mlx --base gemma-4-31b --model mlx-community/gemma-4-31b-it-6bitThe MLX guide, and every path.
Read this
Honest limits
- One box, one sessionEvery race figure is from one RTX PRO 6000 Blackwell Workstation Edition, power limit 600 W (default, enforced), each system on its own server.
- One questionThe one-question figure in the hero is server time, on decisio 0.8.1's served defaults and one RTX PRO 6000 at 585 W, so a card at 600 W may read new states faster.
- Time, not accuracyThe race compares how long fifty questions take, on synthetic support tickets.
- Replayed, not liveThe race replays medians of 5 or 10 documents, and the demo replays decisions recorded on decisio 0.9.0.
- A snapshot of the boardThe ranks are for JevBench v1.6.1; the live board has moved since.
- HardwareGemma 4 31B needs a 96 GB card, or a 64 GB Mac.